Our experimental fork of DroidStar can now decode M17 voice with a neural vocoder. The new decoder comes from Codec2-mod-neural, which uses the FARGAN network from the Opus project. It takes the same Codec2 3200 frames every M17 radio already sends and turns them into wideband 16 kHz speech instead of the classic 8 kHz sinusoidal synthesis. Nothing changes on the transmitting side, the bitstream is untouched, so you get the improvement on every 3200 bps M17 stream you receive, no matter who is talking.
Installing
Download the zipped APK file below.
Unpack it and open the DroidStar.apk file. Android will ask you to allow installs from your browser or file manager – allow it.
If you already have DroidStar installed and Android refuses to update it, uninstall the old version first and install again. Your settings (callsign, hosts) will need to be entered again.
To enable the neural synthesizer, go to Settings and scroll down to “Neural Codec2 decoder (M17 3200)” – tick it. Connect to a reflector afterwards, as usual.
Tell us how it sounds and which phone you use. Waiting for comments!
Codec2 3200 carries M17 voice, and its classic decoder is the weak spot. It’s limited to 8 kHz and has that recognizable buzzy, synthetic sound. Instead of designing a new codec, I wanted to know how far a better receiver could go with exactly the same bits on the air.
The answer is FARGAN, the low-complexity neural vocoder from Xiph’s Opus codec (Valin et al.). The idea is simple. The Codec2-mod decoder unpacks each 8-byte frame into its usual parameters: pitch, voicing, energy and LSPs. Instead of feeding those to the sinusoidal synthesizer, we map them to 20 features per 10 ms and let FARGAN generate 16 kHz speech.
Data: the Opus speech corpus, processed with Opus’s own augmentation recipe, but with features computed by the real Codec2-mod encoder and decoder. An important early lesson: never pair noisy features with a clean target. The network can’t denoise, and my first attempts sounded like speech through a pipe.
Training: Opus’ two stage recipe on rented GPUs1. Stage 1 was 400 epochs (about 14.5 hours), and stage 2 was 50 adversarial epochs (about 37 hours on an RTX 5090). The adversarial stage made a clearly audible difference from its first few epochs.
C library: the model uses about 818,000 parameters, runs on Opus’ own C inference code, and takes about 1.6 ms of CPU time per 20 ms frame on a single x86 core. The ARM64 NEON build compiles and produces matching output, real hardware timing test will follow.
The result is Codec2-mod-neural, a drop-in alternative to codec2_decode(): 8 bytes in, 320 samples at 16 kHz out. Nothing changes for transmitters, and every existing Codec2 decoder still works on the same stream.
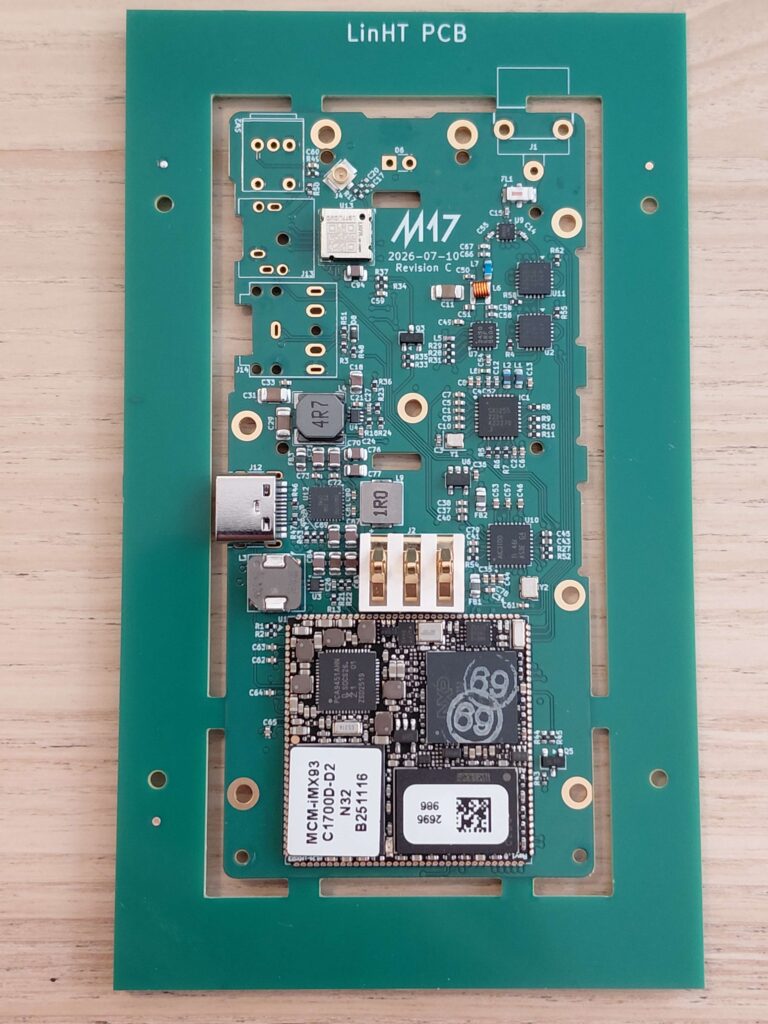
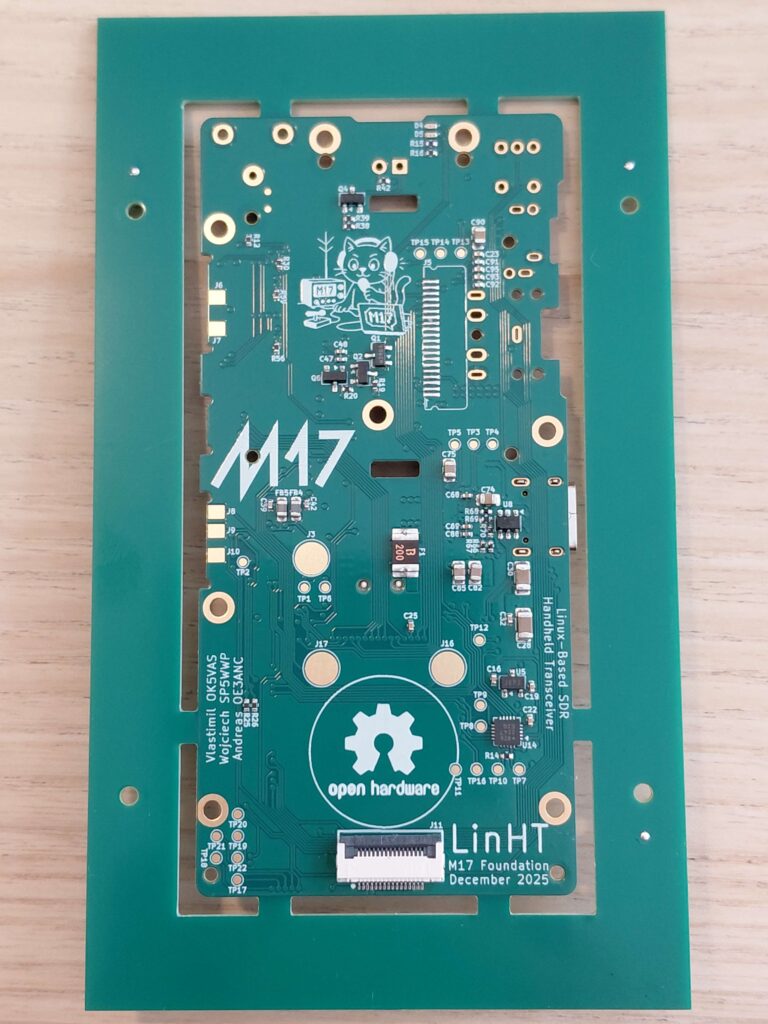
Next up: integration into DroidStar and mvoice, and later a look at running it on LinHT. ViSQOL benchmarks will also be ran along with synthetic BER tests to assess synthesizer’s noise immunity.
M17 Foundation covered the expense (200 USD) with most of it left for future runs. ↩︎
Two recent commits make libm17 (versions 1.4.0 and 1.4.1) a better fit for small microcontrollers, such as the Cortex-M4-based radios OpenRTX runs on.
The first, 5214d99, reduces memory and code size without changing any output. The receive front-end and the Viterbi depuncturing now work in a single pass, and the four convolutional encoders became one. On a Cortex-M4F this reduced the Viterbi decoder context from 1,596 to 620 bytes, decoder stack from about 1.5 KB to 800 bytes, and flash by about 840 bytes. The decoder context changed size, so this is a slight ABI change.
The second, 0c92621, replaces the soft Golay(24,12) decoder used for the LICH with a Chase-II decoder that rejects ambiguous codewords. In simulation, LICH sensitivity improved by about 1 dB, and wrong LICH chunks are accepted 20–80x less often. As a result, decode_str_frame() will report a failed LICH (lich_cnt = 0xFF) more often at low signal levels. On a Cortex-M4, decoding a stream frame takes roughly 30-40% more CPU than before, which is still less than OpenRTX’s own decoder. The same commit uses a hardware popcount where the target has one and makes the unit tests compile without warnings.
LSF, payload and transmit output are unchanged, and the public API is the same. In simulated tests against OpenRTX’s hard-decision frame decoder, libm17 needed about 3 dB less SNR for a successful decode.
To keep the post short, I will only focus on what kind of work has been done so far and provide a few samples for your judgment.
Rationale: we often hear that Codec2 does not sound good, or that it is “no better than other DV modes”, or plain “analog FM sounds better”. Well – sure, Codec2 might not really offer anything better than AMBE/IMBE in the technical sense – all of these vocoders are based on LPC and simple glottal excitations. They sometimes perform better, sometimes worse. A solution to that, while keeping the whole M17 protocol intact, is to change how the speech is reproduced at the receiver.
Motivated by earlier research conducted by Felix Schäfer (DD8SF) – Applications of Neural Vocoding Techniques in Amateur Radio (as presented at the M17 Conference 2025), I decided to train a full GAN network using a LibriSpeech corpus (English). Thank you very much for the groundwork in this field. I decided to pick FARGAN as the reference approach, and apply it onto Codec2-mod, 3200bps mode. Codec2-mod has been selected because it is much more computationally efficient than the reference Codec2 implementation written by David Rowe, VK5DGR, et al. The last step of the FARGAN approach has been intentionally omitted for now (additional fine-tuning with low learning rate).
The idea is this: at the receiver-side, take the Codec2 frame parameters (simply tap in) and pass them to a neural speech synthesizer, instead of the one provided by Codec2. This way the bitstream transmitted over RF stays the same for every M17 user. The only thing that changes is that you can choose the speech synthesizer – the one provided by Codec2, or the neural-network-based one. This enhances the sound quality on your side only. The only limitation is that it requires some computational power, and therefore can not be executed on a plain STM32 (OpenRTX targets). To put it simple – the enhancer works on top of Codec2, without changing or modifying anything else. It can be ran in realtime on smartphones and PCs (vide: DroidStar, mvoice, etc.) at very little CPU cost.
Audio samples, starting with the source recording:
Reference input audio, sampled at 16kHz
The sample below is more or less what the microphone would pick up at the transmitter side.
Reference input audio, resampled at 8kHz
And this is roughly how M17 sounds today. Plain Codec2, 3200bps:
The 8kHz audio sample, Codec2-encoded
The next two files show how FARGAN behaves when it is used as a replacement to Codec2’s synthesizer.
The 16kHz sample shows how the network reconstructs the missing spectral information from the available 8kHz of bandwidth. The bitstream stays the same – 3200bps.
The next step is to bring the finely-tuned enhancer and perform some adversarial training and apply it to the output to, hopefully, make it sound even better and less metallic. After that, I might want to try it on top of DroidStar to see how it works with real Codec2 bitstreams.
Version 2.1 of CARI, the Common Amateur Radio Interface, has just been released. The biggest change as compared with the previous 1.3 is a clean way to end a transmission. The master sends an empty uplink (UL) message, and the device plays every buffered sample, ramps down, and disables its transmitter on its own. The release also turns the remaining open points into firm rules: status precedence, socket binds, supervision edge cases, TX stop, and UL underrun trips. Rebinding or closing the UL socket now discards any unread data. A more complete changelog is available in the commands.md file.
The protocol now has its own C library, libcari. It covers frame encoding and decoding, capabilities, sample scaling and baseband compression (based on FLAC), plus ready-made ZeroMQ slave and master layers. Both tools below are built on it.
cari-dummy-device now emulates the planned SX1255-based RRU v2: one full-duplex I/Q subdevice at 400–510 MHz and 125, 250 or 500 kHz, with FLAC compression and supervision. Its emulated hardware runs in real time, so backpressure and underruns behave as they would on the real board. The tool can be used to develop and test CARI masters without hardware.
cari-ctrl has been rewritten for CARI 2.x. It can inspect and configure a device, capture RX samples, transmit files or test tones, and monitor supervision data, all from one command line. cari-host is now obsolete and the repository is archived (read-only).
It is strongly suggested to download the latest installer and run it. From now on, the installer checks for a newer version of itself on each run, so this manual download is needed only once.
Dashboard:
security fixes: changing settings requires a password, shell injection and arbitrary file reading and writing through the config paths are fixed, CSRF protection on all forms
RF signal quality is now shown as bit error rate (BER), averaged over the whole voice stream, with color thresholds from a noise-limited test, and the M17 hostfile comes from the new source and is only downloaded when it has changed (thanks to Jim N1ADJ)
renamed a couple of menu entries
times use the configured timezone
the “Max. text messages” setting now works
expired map markers are removed
TX power is read from the config instead of being hardcoded
the reflector and radio status is now correct regardless of when the connection was made
added a “Device control” panel with reboot/shutdown buttons
the last element on each page no longer sits under the fixed footer
The installer script:
the script automatically sets the modem type based on user input
the web server can write only config.php and files/, no longer the whole dashboard directory
nginx: it now blocks web access to the dashboard’s files/ directory
Finally, after all these years, we have reached a point where everything seems to work. That’s the 1.0.0 reference point. I would like to express my sincere gratitude to Jean-Michel Friedt for all the help that he provided.
Recent changes include:
Build: clean on GNU Radio 3.10, with the submodules updated (Codec2-mod, micro-ecc, libm17)
Dialogs: tidy, with hex key entry, all META types, and the decoder following the received stream
Encoder: correct SOT/EOT/SMS messages handling, a reliable stream loop, “continuous mode” (running without external message control, basically what we had before), multi-block Text Data, and SMS up to 821 bytes
Signing, scrambler, and AES now work end to end, and were checked independently against an external ECDSA reference, the spec’s LFSR polynomials, and Python’s cryptography AES
Decoder output is defined for unusable frames: Codec2 silence, chosen by listening (replacing invalid frames with zeros or inserting silence both sound worse)
Console output is readable and consistent (a lot of cleanups)
Categorization: we split the M17 part from Codec2
Side effects (positive!):
Spec: the scrambler section was clarified, and the AES counter contradiction fixed
M17_Implementations: the LSF CRC bug in m17-coder-sym is now fixed